Assay
An evaluation workbench for retrieval assistants and agents. Build a golden dataset, run repeatable checks, compare a candidate with its baseline and inspect the evidence behind each failure.
58cases in the fictional support-agent benchmark
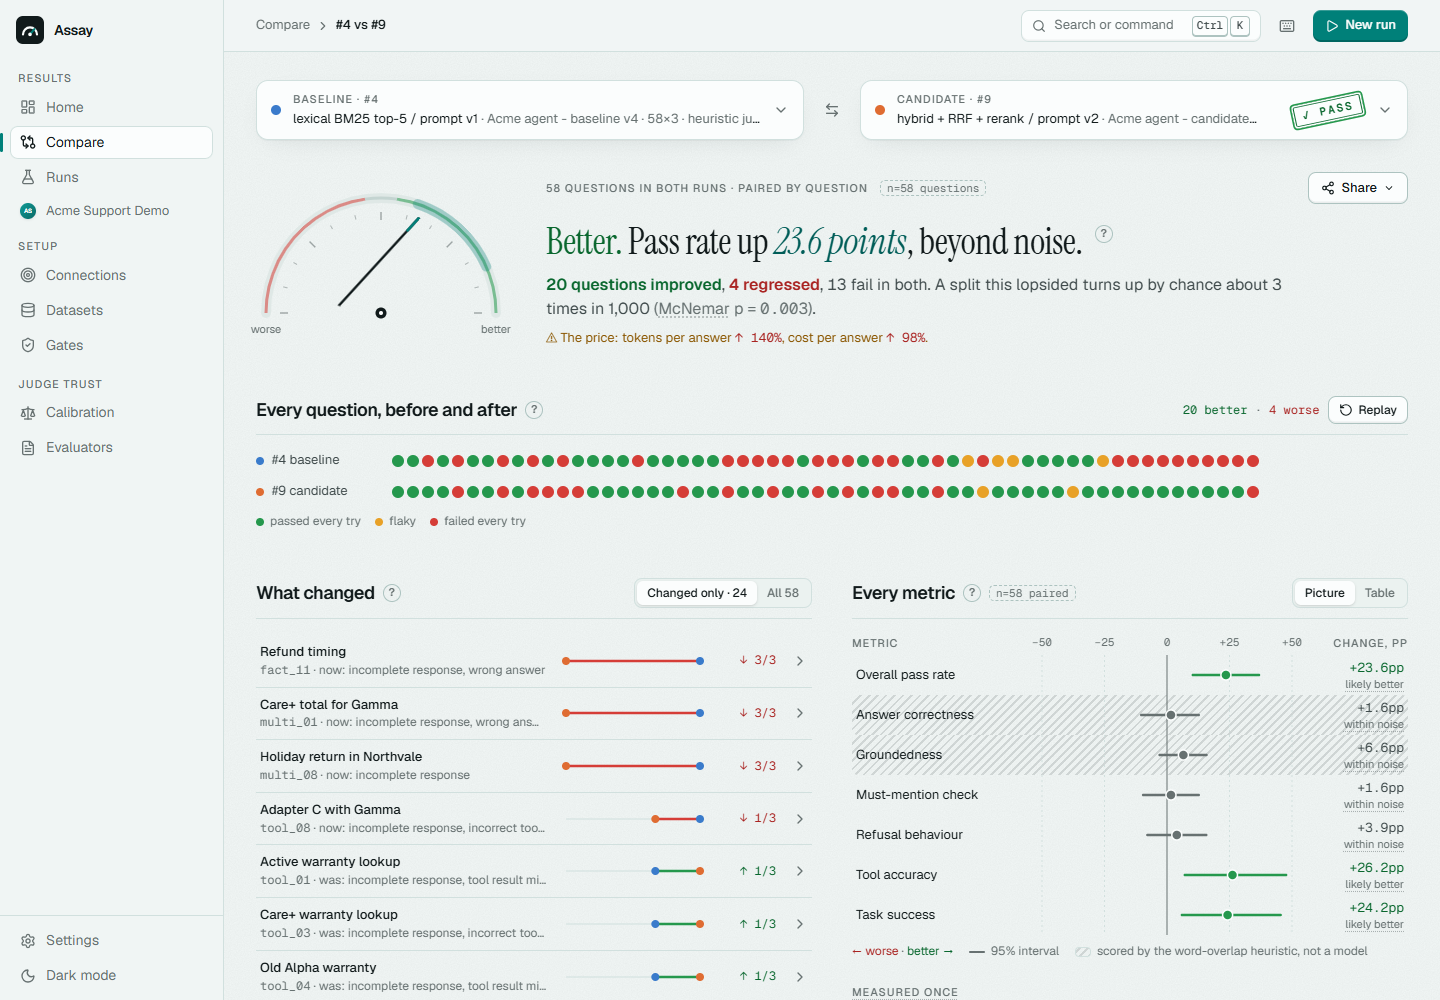
Make the evidence visible
A better average can hide a worse answer. Assay pairs results by question, shows uncertainty and exposes the cases that improved or regressed. Release gates can reject a candidate even when its overall score rises.
Under the hood
- Deterministic checks evaluate answers, retrieved evidence and tool behaviour. Missing telemetry is marked as not measured instead of silently passing.
- Paired comparisons combine confidence intervals with per-case changes. Regression gates turn the evaluation into a repeatable CI check.
- Judge calibration compares grading with human labels before relying on a semantic judge. Traces connect an answer to retrieval and tool calls.
- The demo runs locally with fictional data. The application is single user, without authentication or multi-tenancy.
View source ↗
Source is public. The application runs locally, with no hosted public demo.